First Token Latency vs Throughput Trade-Offs in Local Inference
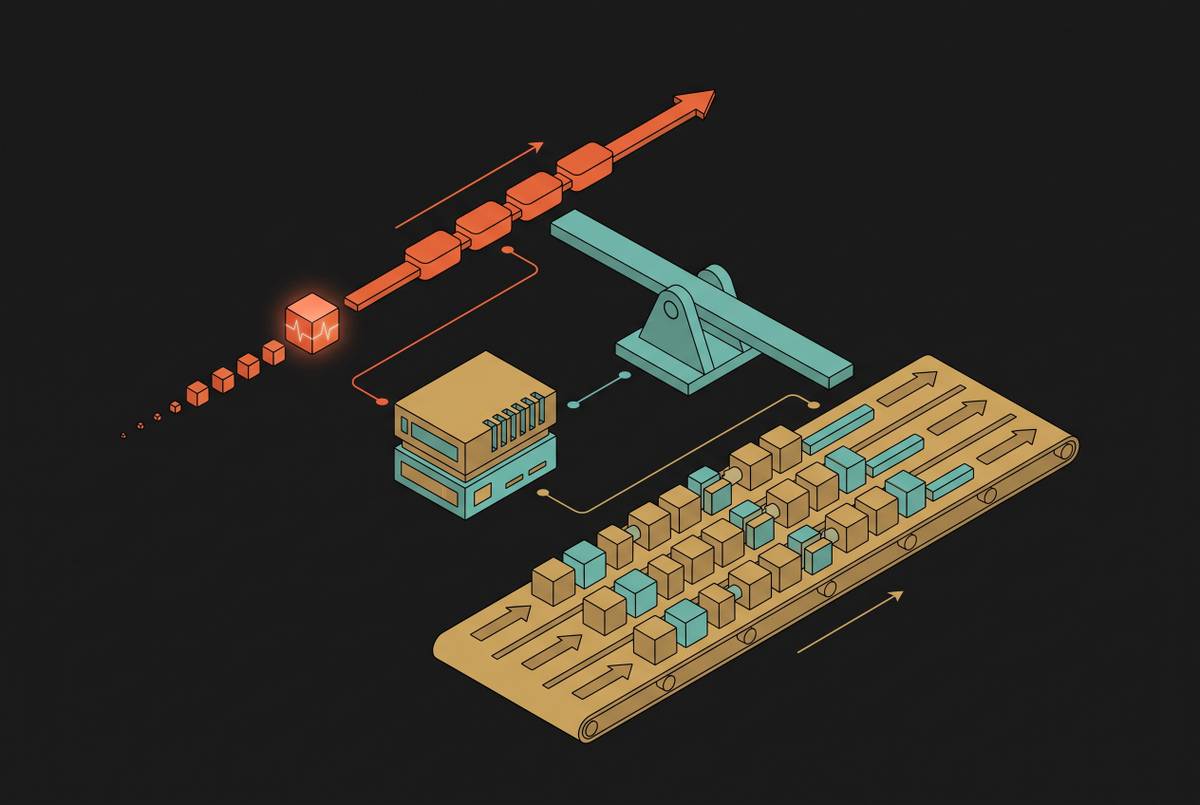
Optimizing for speed requires choosing between fast first tokens or high output volume.
Tobias Gerhart
Section
7 stories in Model Benchmarks.
Optimizing for speed requires choosing between fast first tokens or high output volume.
Memory bandwidth, not raw compute power, determines how fast GPUs generate tokens.
Benchmarking reasoning models requires measuring hardware constraints, not just accuracy scores.
Separating groundedness, completeness, and factual accuracy reveals what ROUGE scores miss.
Small local models excel at routine coding tasks but struggle with complex multi-step work.
Local models fail structured tasks through logic, timing, and uncertainty—not just format.
Effective context capacity runs 60-70 percent of advertised maximums in production systems.